Explore our Blog for
Latest News & Insights
Stay updated with the latest updates and new products. Discover what's happening around the io.net.
io.net blog
Latest
See All
The big AI access question isn't which model you can use, but rather whether. you can get the compute to build, fine-tune, or run anything at all. As AI infrastructure investment climbs toward what many analysts describe as tens of trillions of dollars in projected spending over the coming decades, the infrastructure beneath that spending is consolidating rapidly into a small number of hyperscale build-outs serving a small number of well-capitalized buyers. The result is a structural access gap
Ask anyone about how to solve AI compute scarcity and they’re likely to lean into a default answer: build more data centers. More campuses with a ton of gigawatts fueled by dedicated power substations. But in 2026, that answer is running headlong into a wall of physical and financial problems that simply weren’t very visible a couple of years ago. Grid interconnection queues now stretch 5–10 years in many regions across the US. For those AI data center projects in the pre-grid phase, diesel
The financialization of GPU infrastructure is quietly reshaping who controls AI compute access. As datacenter operators and neoclouds use GPU fleets as loan collateral to finance billion-dollar buildouts, capacity allocation is starting to follow debt-service logic rather than market demand. The result is that access concentrates around well-capitalized incumbents while startups and independent researchers face a compute market where the best bid doesn't always win the capacity. Distributed supp
The most important AI infrastructure decision in 2026 is not which model scores highest on MMLU. It is whether the model you deploy creates a new dependency on a vendor, a pricing tier, or a compute layer that trades one form of lock-in for another. The open-vs-closed line has shifted enough over the past 18 months that the old framing ("open models are catching up to closed ones") no longer captures what's actually happening. For many workloads, open-weight models from Llama, DeepSeek, Z.ai,
We’re told that AI's compute crisis is a supply problem. That is, simply not enough GPUs exist. AWS is reportedly planning millions more chips, NVIDIA is backing gigawatt-scale "AI factories," and analyst estimates suggest a capex supercycle unlike anything the industry has seen. While a global chip count shortage would seem to be the most likely suspect for AI workload constraints, the truth has a bit more layers. In fact, a significant fraction of existing GPU capacity actually sits idle.
AI's power problem has two very different answers, and the industry is currently sprinting toward only one of them. Understanding the distinction matters for anyone making GPU sourcing decisions in 2026, because the math on each path looks very different depending on where you stand. The dominant industry response to AI's energy demand is new-build in the form of gigawatt-scale campuses, dedicated power infrastructure, long-term purchase agreements. That approach adds supply by constructing it
The AI budget conversation is the hot topic this year. So, it’s safe to say that If you've probably heard some version of this line: token costs are falling fast and AI is about to get a lot cheaper. It's a reasonable proposition. You want to believe it. But according to Gartner's own research, it’s a notion that is mostly wrong for the people actually paying the bills. Gartner's forecast, published this spring, makes some other striking proclamations. By 2030, they believe that running infer
Let’s imagine that you’ve budgeted $10,000 for an AI/LLM training run. You hop on AWS and the app says, “no H100s available for 72 hours”. Apart from some stress and frustration, what does that delay actually cost your team? In answering that question, perhaps like Thanos, when asked by Dr. Strange how much it cost to collect the infinity rings, he replied: “Everything”. All joking aside, most finance models would record “zero”. There’s no invoice because you’ve consumed no GPU-hours. Your $10
When you ask an AI to help with something and it refuses, that refusal didn't happen by accident. Someone, or more precisely, a team of researchers, lawyers, and ethicists at a major AI lab, made a deliberate choice to build that boundary into the model. Today, major model providers (e.g. OpenAI, Anthropic, Google, Meta, Mistral, and Cohere) each maintain their own alignment teams, each with distinct values, risk tolerances, and commercial pressures shaping what their models will and won't do. T
Let’s imagine that you’ve budgeted $10,000 for an AI/LLM training run. You hop on AWS and the app says, “no H100s available for 72 hours”. Apart from some stress and frustration, what does that delay actually cost your team? In answering that question, perhaps like Thanos, when asked by Dr. Strange how much it cost to collect the infinity rings, he replied: “Everything”. All joking aside, most finance models would record “zero”. There’s no invoice because you’ve consumed no GPU-hours. Your $10
io.net is utilizing the Solana blockchain for instant GPU payments, smart contract automation, and secure, decentralized cloud computing transactions.
Learn what a GPU cluster is, how it differs from multi-GPU servers, and use our cost calculator to decide if you should build or rent one.
Your 2026 guide to building a purpose-built GPU cluster for AI. Includes TCO, vendor-agnostic benchmarks, hardware selection (H100/MI300X), and rollout plan.
Complete technical guide to decentralized compute: benchmarks, cost calculator, compliance checklist, and step-by-step migration from AWS/GCP.
Discover io.net's Incentive Dynamic Engine (IDE): an adaptive tokenomics model bringing sustainable economics and predictable stability to decentralized GPU compute.
New io.net study shows consumer GPUs (RTX 4090) can cut AI inference costs by up to 75% for LLMs, enabling a sustainable, heterogeneous compute infrastructure.
Blockchain promised to solve centralization, but focused on wrong problems. DePIN networks like io.net finally deliver real value through affordable GPU access.
Latest By Topic (138)
See All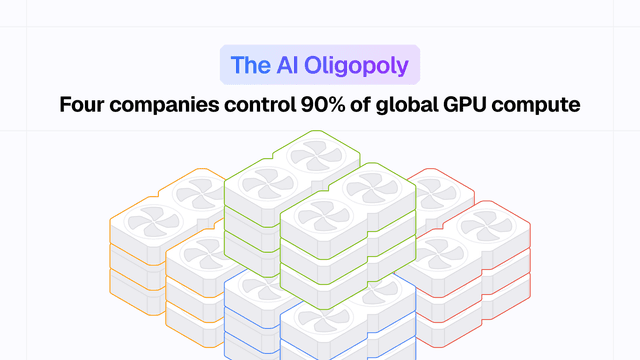
Four companies control 85–92% of the GPU compute powering commercial AI training and inference globally. But there is a way around this monopolistic control and GPU hoarding.
RunPod has a reputation for being the GPU solution for the "instant-deploy" developer. Its intuitive "Pods" and robust serverless GPU offerings make it a good fit for startups and hobbyists who frequently prototype. Whereas legacy providers focus on enterprise contracts and academic researchers stick to boutique clouds, RunPod captured the mid-market by mastering serverless GPU compute and container-based flexibility. Its reputation is built on "FlashBoot" technology (sub-200ms cold starts) and
GPU cloud costs have climbed steadily since 2022, and most developers don't really understand why. An NVIDIA H100 SXM on AWS (p4d.24xlarge equivalent) runs roughly $32–$36/hr on-demand. The same GPU on io.net costs $2.99/hr. That amounts to a 10x gap.
On June 11th, io.net's third anniversary, we launched the Incentive Dynamic Engine (IDE). Not a roadmap, not a litepaper. Live, on-chain, utility driven, and fully transparent. A month in, here's another look at what the IDE is, why it matters, and what's happened since. What the IDE does Most token networks grow the same way. They pay suppliers with emissions, and hope demand eventually catches up to justify the supply. It works until it doesn't. When the token price drops, suppliers leave
For infrastructure decision-makers at both startups and growing companies, the GPU landscape of 2026 looks nothing like it did even last year. The mad dash for GPU capacity has now matured into a $140B+ global market defined by architectural diversity, pricing pressure, and a fundamental reevaluation of how compute should be provisioned. As these three forces converge, we are seeing GPU supply expand. While hyperscaler buildouts capture a lot of attention, there has also been a rise in decentr
The AI landscape of 2026 is now more of a battle of over infrastructure instead of a clash of models. For many AI/ML developers, CoreWeave has been the reliable "specialized" choice for NVIDIA hardware. However, as the "Power Wall" of 2026 makes electricity and high-density data center space more precious than the chips themselves, many startup and enterprise teams are searching for alternatives that offer both better availability and more affordable pricing. So, if you’ve been priced out by Co
Frontier AI training, or models with 70B+ parameters, multimodal architectures, MoE variants, requires GPU clusters operating at a scale most teams just can’t self-host. On io.net, AI teams don’t even have to think about self-hosting your compute, or paying hyperscaler prices. You can effortlessly spin up a distributed cluster of H100s or A100s in minutes, paying $1.49–$2.29/hr per GPU with no reserved-capacity commitment. Instead of all of the overhead costs that come with self-hosting, you c
There's a specific moment every ML engineer has dreads. In the early morning hours, after finishing the debugging of a data pipeline, you’re just about to run an experiment that requires 8 H100s for roughly 6 hours. After hopping on your cloud console, you click through the instance request, and see this message: "Your request for p5.48xlarge has been denied. Current quota: 0. Request quota increase." The thing is, that quota increase takes 3-10 business days. So, your experiment waits. A
Learn what a GPU cluster is, how it differs from multi-GPU servers, and use our cost calculator to decide if you should build or rent one.
When LLM agents started performing automated tasks, their architects failed to mention that they consume compute in ways that are fundamentally different from your usual DevOps pipeline. In a conventional web service, there is a predictable compute profile. Requests come in, get processed by known-size containers, complete, and then this process repeats. Traditionally, autoscaling at the edges is well-understood, so that your company’s infrastructure team can model capacity, set alarms, and sle
KayOS, an AI startup, achieved 5x developer power with io.net. Learn how their 2-person team cut compute costs by 60% ($2.5k to $1k/month) using io.intelligence.
AI has already changed the world. But, for it to reach its full potential, issues of accessibility and affordability need to be addressed. It needs to happen soon, before the industry leaves a huge swath of devs and builders from around the world behind. AI teams need infrastructure that allows them to get their product to market, not burn through their runway before they ever get off the ground. Models are growing exponentially. Llama 3.1 405B requires 16,000 H100 GPUs for training, GPT-4 tak